Usage
Usage tab This tab connects Storybook documentation with live product usage, references, and deviations
Infa Storybook Addon


A Storybook addon that connects your component documentation with real-world product usage. See where and how your design system components are actually being used across your products—directly in Storybook.
What it looks like
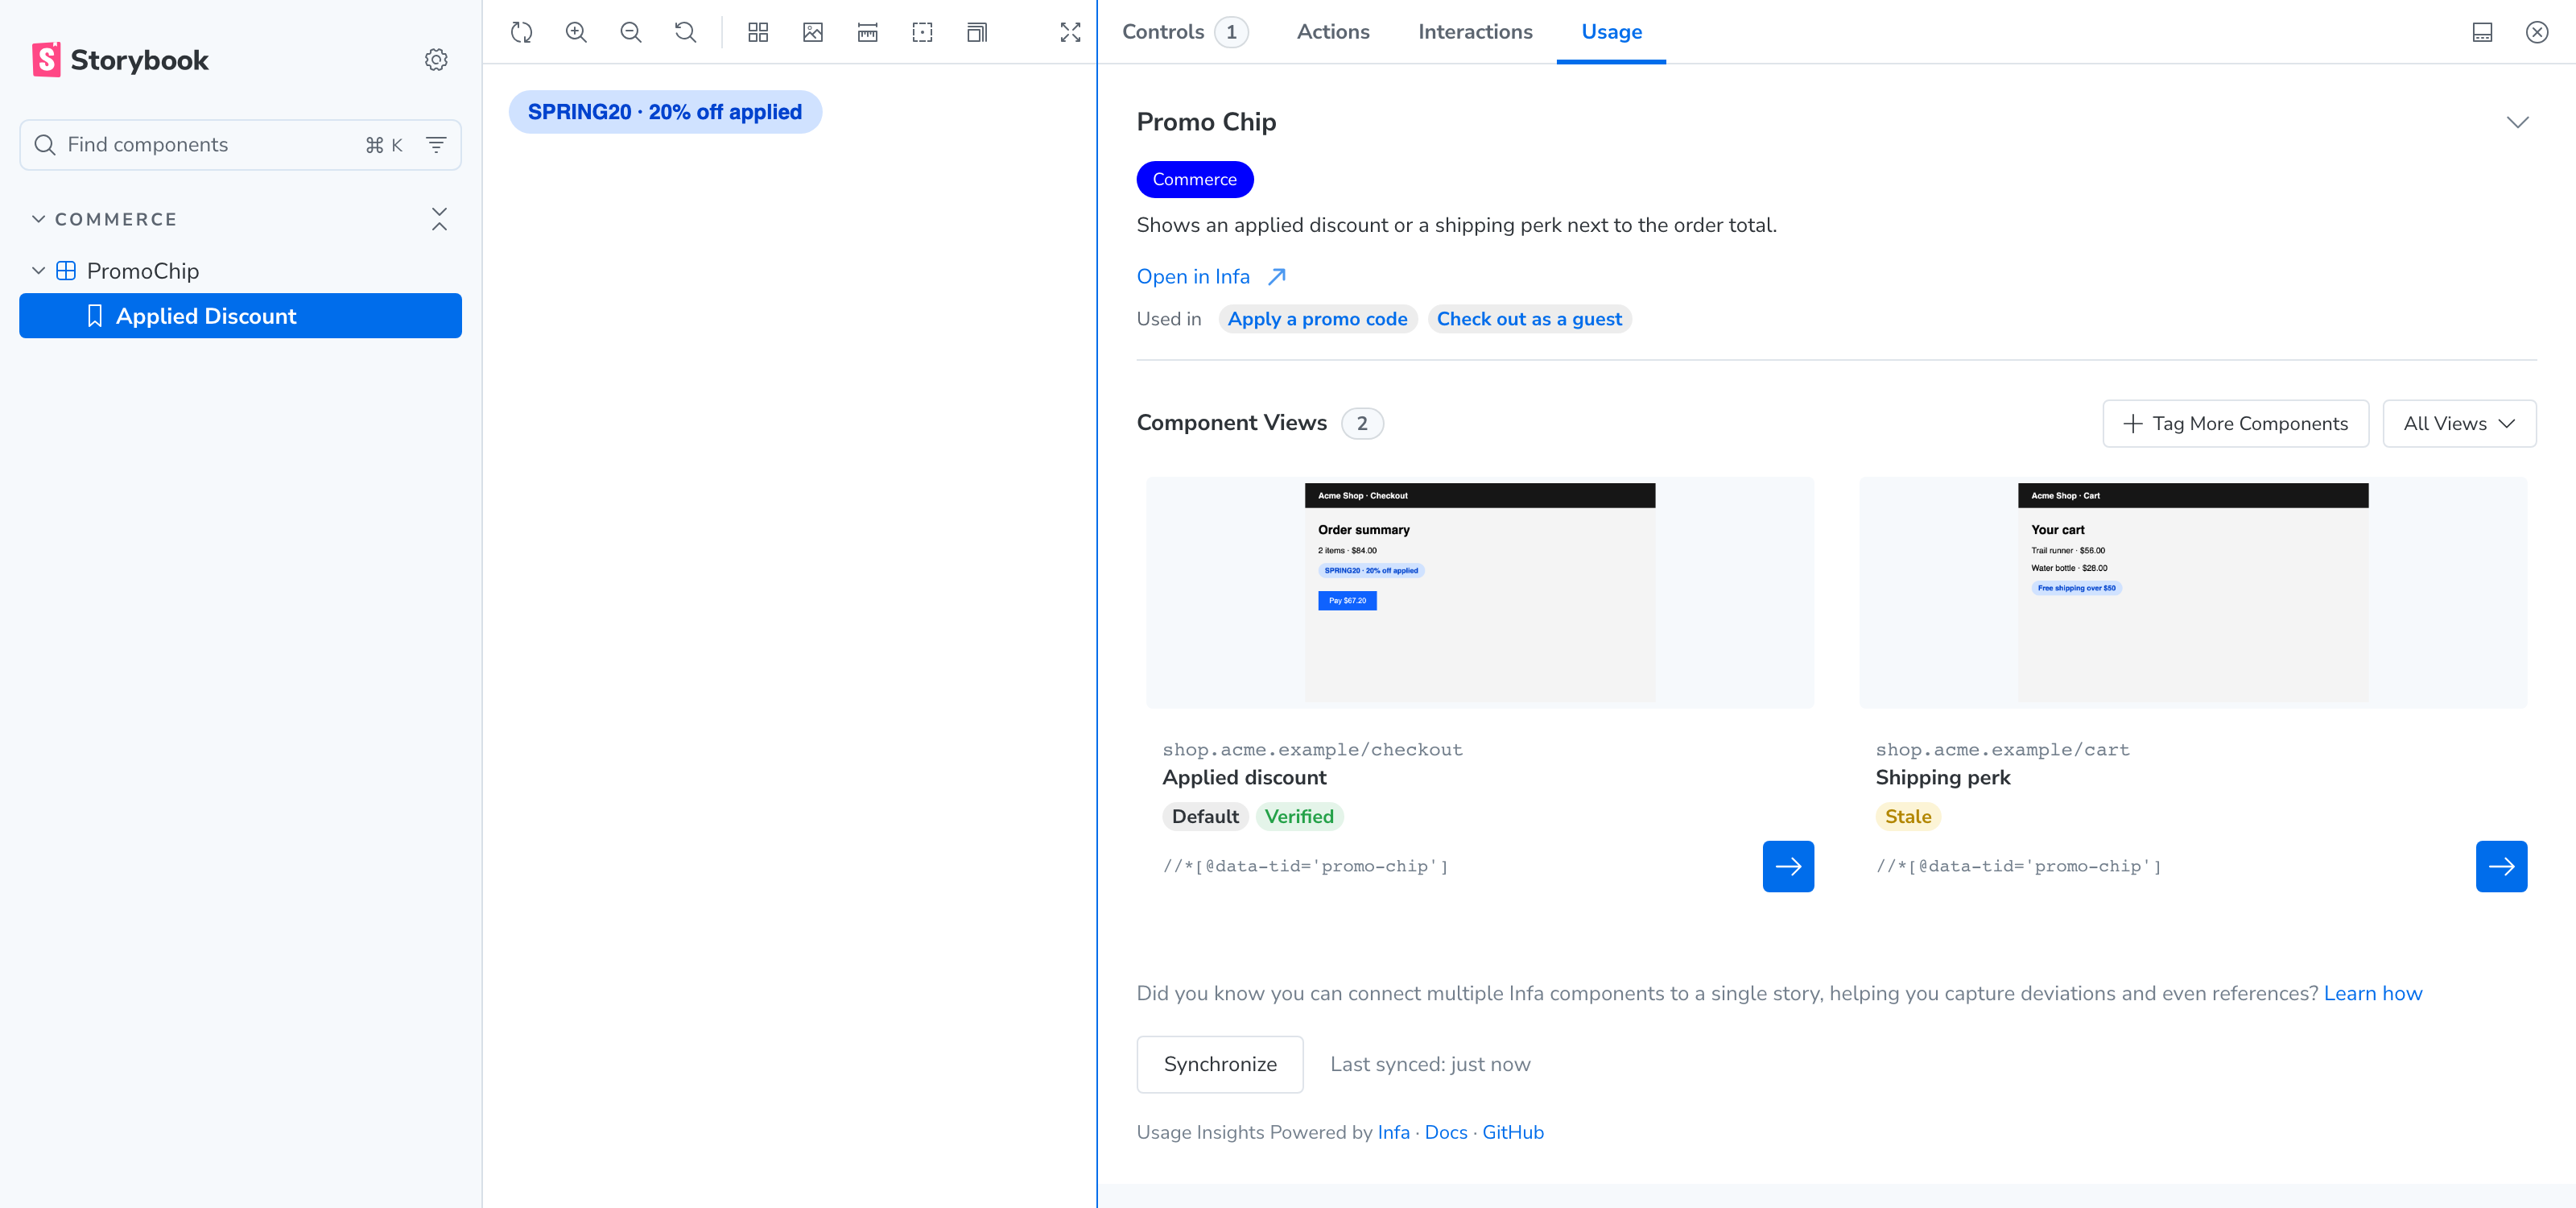
In Storybook: the Usage tab of a story shows the component as your Infa board knows it: its label and description, the flows that use it, and its usages — each place in your product where it is used, grouped by the screen it is on — with a screenshot, whether it was found in the Browser (the Chrome extension) or in Code (the Infa CLI), where exactly (the page, or the file), whether it is the default view, and whether it is still found there (Verified) or has drifted (Stale). Open in Infa goes to the component on the board.
Under them, In code lists every place your code renders the component, read from the repo with nothing to tag: each call site's file and line (linked to it on GitHub or GitLab), the element as written and the component it sits in, grouped by the board screen its route is (else the route, else "Not on a route"), with how its props are passed (variant: primary ×8, danger ×3).
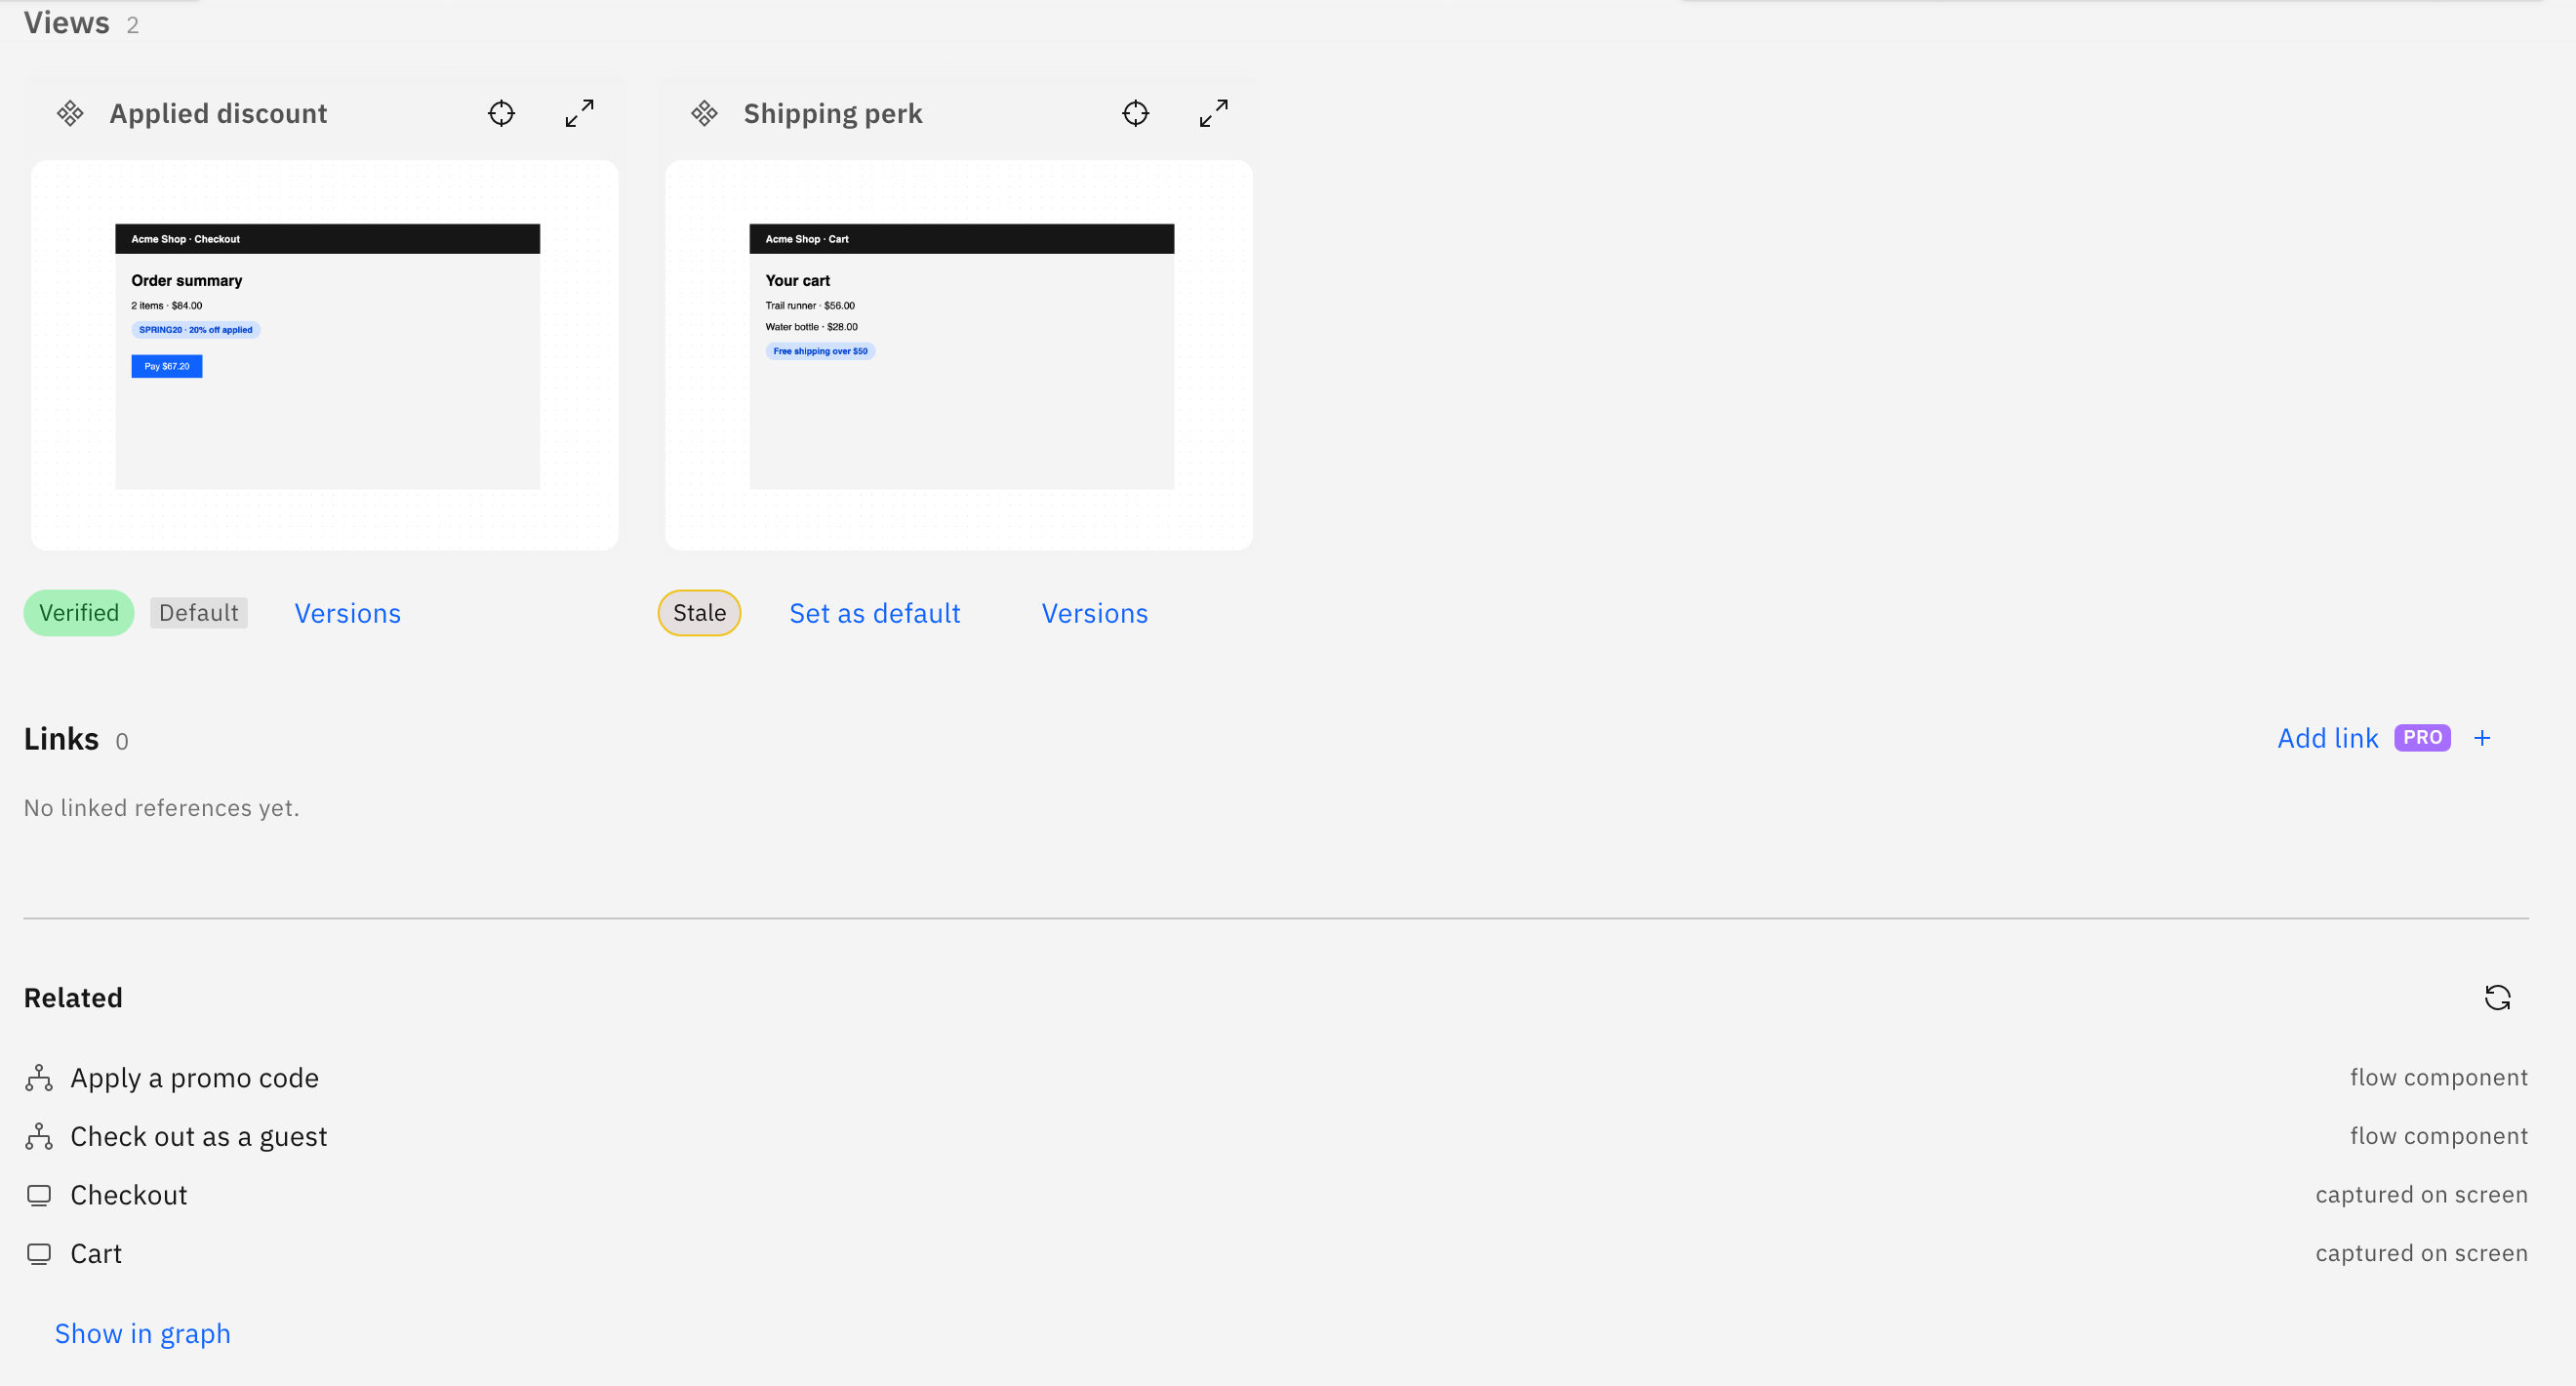
In Infa: the same component on its board page: its views with the same status, and the flows and screens it is related to.
The Problem
Design system teams often struggle to connect Storybook components with their real-world product usage. While Storybook provides a centralized place to document and showcase components, it doesn't show:
- Where components are actually used across product UIs
- Whether they're used consistently or with deviations
- How often they appear, and in which product contexts
- Adoption metrics per product and page
This creates a gap between design documentation and reality, making it challenging to communicate adoption, identify inconsistencies, and prioritize refactoring efforts.
The Solution
The Infa Storybook Addon adds a Usage panel to every story, connecting Storybook component previews with live product usage data. This empowers teams to:
- See real usage instances of components across products and pages
- Identify deviations and variants using labels (e.g., "Deviation", "To Refactor", "Reference")
- Track adoption per product and page (coming soon: visual real estate ratio, DOM nodes ratio)
- Collaborate with context - share not just the component, but where it lives in production
- Tag components in browser - all data syncs via API during build time
Storybook remains your component playground and source of truth, while Infa serves as the adoption and usage discovery engine. This addon bridges them seamlessly.
Features
- Display actual usage instances with product URLs, XPaths, and screenshots
- Organize components with labels (deviations, references, refactoring candidates)
- Connect external documentation and design system resources
- Secure build-time data injection (no API keys exposed to browsers)
- Framework-agnostic
How It Works
The addon consists of two parts that work together:
Part 1: CI/CD Data Fetching (Build-Time)
A Node.js script that runs during your build process (locally or in CI/CD):
- Scans your story files for Infa main component IDs
- Fetches component data from the Infa API (title, description, usage instances, labels, etc.)
- Generates
src/data/usage-data.jsonwith the fetched data
Key Benefits:
- Full Control: Runs at build time, giving you complete control over when data is fetched
- Secure: Your Infa API key never gets exposed to the browser or end users
- Always Fresh: Tag new components in Infa, rebuild Storybook, and immediately see them in the Usage panel
- No Runtime Dependencies: No API calls from the browser, keeping your Storybook fast
Part 2: Storybook Addon (Browser)
A Storybook addon that runs in the browser:
- Reads the pre-generated
usage-data.jsonfile - Displays component usage information in a dedicated "Usage" panel
- Shows where components appear in your products with visual evidence
Prerequisites
- An Infa account and a board with your components on it — published from code with the Infa CLI (
infa publish) or tagged in your product with the Infa browser extension. Personal and team boards both work. - Get started at: infa.ai
Good news: Once you've tagged your components and added deep links, they'll continue to work even after subscription deactivation. You'll still be able to see where and how components are used in your products.
Installation
npm i storybook-infa-usage
Quick Start
1. Register the Addon
Add to your .storybook/main.ts:
// .storybook/main.ts
import type { StorybookConfig } from "@storybook/your-framework";

const config: StorybookConfig = {
  addons: [
    "@storybook/addon-docs",
    "storybook-infa-usage", // Add this line
  ],
};

export default config;
2. Sign in with the Infa CLI (once)
From your project's root:
npx infa auth    # opens the browser; the session is saved in .infa/config.yml (gitignored)
npx infa board   # picks the board this repo belongs to
You sign in as yourself, so the addon sees exactly what you see on the board — a team board included. There is no key to copy and no header to set.
3. Put your components on the board
Publish a component (every view of its .preview.tsx sidecar or stories) with the CLI:
npx infa publish src/components/Button.tsx
That is also what links each story to its component: the CLI records the component's id in the sidecar (infa.componentId) and .infa/components.yml, and infa storybook sync reads it from there. Your stories need no ids.
Components you tagged in your product with the Infa browser extension can be named in a story instead — see Naming components in a story.
4. Sync the usage data
npx infa storybook sync
It finds your *.stories.* files, works out the board component each one documents, reads those components from the board and writes src/data/usage-data.json:
◇  Read 2 component(s) from b_abc12345
●  src/components/Button.stories.tsx → mc_abc12345 (sidecar infa.componentId)
●  src/components/Card.stories.tsx → mc_def67890 (mcComponentIds)
└  Wrote 2 component(s) to src/data/usage-data.json. Restart Storybook to see them.
A story's components are, in order: the mcComponentIds it names, then the component it renders as the CLI knows it — its sidecar's infa.componentId, .infa/components.yml, the legacy @infa-component annotation, and finally the one board component whose views were published from that file. Options: --out <file>, --stories <dir>, --ids mc_a,mc_b, --board <id>, --dry-run, --json.
The same sync reads your code for In code: every place it renders each story's component (renamed imports, barrels, UI.Button, lazy(), styled(Button) included; tests and stories not), and the route each one is on (Next.js app/ and pages/, React Router), matched to your board's screens. If your design system is its own package used by other repos, point the sync at them: npx infa storybook sync --in ../shop,../admin (their imports of your package name count). --no-code skips it. In the terminal, npx infa usages Button prints the same list. To run it as an npm script:
{
  "scripts": {
    "usage:sync": "infa storybook sync"
  }
}
If you write the file somewhere else, tell the addon where:
// .storybook/main.ts
addons: [{ name: "storybook-infa-usage", options: { dataFile: "data/usage.json" } }],
5. Run Storybook
npm run storybook
Open a story and check the Usage panel. Storybook reads the data file when it starts, so restart it (or rebuild) after syncing.
Naming components in a story
A story can name its components explicitly — needed for components tagged in your product (they have no file in your repo), and always honoured alongside what the CLI finds:
// Button.stories.tsx
import type { Meta, StoryObj } from "@storybook/react";
import { Button } from "./Button";

const meta: Meta<typeof Button> = {
  component: Button,
  parameters: {
    usage: {
      mcComponentIds: ["mc_abc12345", "mc_def67890"], // Infa main component ids
    },
  },
};

export default meta;
A component's id is in its URL on the board: https://infa.ai/b/<board>/components/mc_abc12345. Story-level parameters.usage overrides the meta's, as with any Storybook parameter.
Older setup: a Personal Access Token
Before the CLI, the data came from a Personal Access Token and the bundled infa-usage-fetch command. It still works, with two limits: it reads only components on boards the token's own account owns (not a team board you are a member of), and every story must name its mcComponentIds. Prefer infa storybook sync.
- Open infa.ai/profile?tab=integrations (avatar → Profile → Integrations), and under Personal Access Tokens click Generate New Token.
- Click the token's copy button. The table shows only the first four characters (
abcd****); copying that text gives a key Infa does not recognise. - Set it as
INFA_API_KEY(shell, CI secret, or a.envfile in your project root) and run:
INFA_API_KEY="<your 64-character token>" npx infa-usage-fetch
Options: --stories <dir>, --out <file>, --ids mc_a,mc_b. No extra dependencies (Node 18.17 or later).
Calling the API yourself
The command calls one endpoint. To call it from your own code, send your token as the x-api-key header, plus the public apikey header every Infa API request carries (it is the same for everyone; copy it from scripts/infa-integration.js or the API docs):
curl -X POST https://api.infa.ai/rest/v1/rpc/get_storybook_main_components \
  -H "apikey: <public key from the docs>" \
  -H "x-api-key: $INFA_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"p_mc_component_ids": ["mc_abc12345"]}'
The other endpoints (get_main_components, get_component_views, get_boards, …) take the same two headers: see the Infa External API docs.
Fetching Usage Data from Infa
The sync runs at build time, giving you full control over your data pipeline: no credential ever reaches the browser.
The Workflow
- Put components on the board -
npx infa publishfrom code, or tag them in your product with the Infa browser extension - Sync -
npx infa storybook syncreads them as you and maps each story to its components - Rebuild Storybook - The Usage panel immediately shows them
This build-time approach means you can continuously tag new components in Infa and see them in Storybook with a simple rebuild—no code changes needed!
What Data Gets Fetched
The sync reads, for each component your stories document:
- Title & Description: Component name and documentation
- Component Views: Actual instances where the component appears in products
- Product page URL
- XPath location in the DOM
- Screenshot (if available)
- Visual context of where users see this component
- Labels: Tags for organization (e.g., "Deviation", "Reference", "To Refactor")
- External Links: Links to design docs, component libraries, or other resources
- Query: CSS selector or query used to identify the component
- Default view: the component's default view comes first, marked "Default"
- Live render: views published with
infa publishcarry their interactive render; the panel plays it on demand ("Live"), in a sandbox - Element health: whether each view's element is still found on the product — Verified, Recovered, Stale, Broken or Removed — as the Infa extension and
infa flow runlast checked it - Flows: the user flows that use the component (declared on the board, or exercised by their tests), linked to the board
- In code (
code_usages): every place your code renders the component — file, line, the element, its props, the component it sits in, and the routes it is on (each matched to a board screen when the board has one); read from the repo, not the board
Anything the board does not have is left out, and the panel shows nothing for it. The PAT command (infa-usage-fetch) fetches the first six only.
Component Views Explained
Component Views are the heart of this addon. Each view represents a real instance of your component in a product:
- URL: The exact page where the component appears (e.g.,
https://yourapp.com/dashboard) - XPath: The DOM path to locate the component (e.g.,
//*[@id="primary-cta"]) - Screenshot: Visual proof of the component in context
- Title: Descriptive name (e.g., "Dashboard Primary CTA", "Login Button")
This lets you see not just that a component is used, but where and how often across your product landscape.
Upcoming Adoption Metrics
We're adding quantitative adoption tracking:
- Visual Real Estate Ratio: Percentage of screen space occupied by the component
- DOM Nodes Ratio: Proportion of DOM nodes belonging to the component
- Per-Product, Per-Page Tracking: See adoption metrics broken down by product and page
These metrics will help you demonstrate actual adoption—what users see, not just what's in Figma or code repositories.
Automated Data Fetching (Recommended)
Integrate data fetching into your CI/CD pipeline so usage data is always fresh:
# .github/workflows/storybook.yml
name: Build and Deploy Storybook

on:
  push:
    branches: [main]

jobs:
  build:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4

      - name: Setup Node
        uses: actions/setup-node@v4
        with:
          node-version: "22"

      - name: Install dependencies
        run: npm ci

      - name: Sync usage data from Infa
        env:
          INFA_ACCESS_TOKEN: ${{ secrets.INFA_ACCESS_TOKEN }}
          INFA_BOARD_ID: ${{ vars.INFA_BOARD_ID }}
        run: npx infa storybook sync

      - name: Build Storybook
        run: npm run build-storybook

      - name: Deploy
        # Your deployment step here
        run: npm run deploy-storybook
Best Practices:
- Add
src/data/usage-data.jsonto.gitignoreand fetch fresh data in CI. This keeps your repo clean and ensures data is always up-to-date. - A CI runner has no browser to sign in with: set
INFA_ACCESS_TOKEN(an access token from your Infa profile) as a secret andINFA_BOARD_IDas a variable. The CLI uses them instead of.infa/config.yml, and never refreshes or saves them - Nothing secret is written into the data file or reaches end users
- Tag new components in Infa anytime, then rebuild to see them instantly in Storybook
Understanding the Usage Panel
For each component a story documents, the Usage panel displays:
1. Component Overview
- Title: Component name from Infa
- ID: Main component ID for reference
- Description: Full component documentation (supports markdown and images)
2. Usages
A usage is one place in your product where the component is used: a component view that sits on a board screen. Usages are found two ways, and the panel lists both in one list:
- Browser — tagged on a live page with the Infa Chrome extension. Its source is the element's XPath.
- Code — found in your repository by the Infa CLI (or the Claude plugin). Its source is the file, as a repo-relative path.
The list is grouped by screen (the screen's name links to it on the board); usages not placed on a screen yet are grouped last under Not on a screen yet. The group menu also offers Group by Domain (when usages span several sites) and All Usages (one flat list).
Usages (7)                               Group by Screen ▾
  Checkout  2
    [BROWSER] app.yourcompany.com/checkout
              //*[@id="pay-button"]              (the XPath, on a quieter line)
    [CODE]    src/features/checkout/PayButton.tsx
  Not on a screen yet  1
    [BROWSER] app.yourcompany.com/settings
Each usage gives you:
- Where it was found (Browser or Code) and its locator: the page for the browser (with the XPath underneath, full text on hover), the file for code
- A screenshot, or the live render when the view has one
- A link to the component on the board
A component with no usages yet says so, with a link to the component on the board, where usages are added from the browser (Chrome extension) or from code (Infa CLI / Claude plugin).
3. Labels
Organize and categorize components:
- Deviation: Component used differently than designed
- Reference: Good example to follow
- To Refactor: Needs updating to match design system
- Custom labels: Create your own in Infa
Labels help you:
- Identify inconsistencies across products
- Prioritize refactoring work
- Share examples with your team
4. External Links
Quick access to related resources:
- Design system documentation
- Component library (e.g., React Storybook)
- Figma designs
- GitHub repositories
5. Query
CSS selector or DOM query used to find the component in products. Useful for developers investigating usage.
Data File Format
The generated src/data/usage-data.json follows this structure:
{
  "mc_abc12345": {
    "title": "Primary Button",
    "description": "Main call-to-action button used across products...",
    "query": "button.btn-primary",
    "external_links": [
      {
        "title": "Design System Docs",
        "url": "https://design.yourcompany.com/button"
      }
    ],
    "labels": [
      {
        "title": "Reference",
        "description": "Good implementation example",
        "color": "#10b981"
      }
    ],
    "component_views": [
      {
        "title": "Dashboard CTA",
        "url": "https://app.yourcompany.com/dashboard",
        "x_path": "//*[@id=\"main-cta\"]",
        "screenshot": "https://cdn.infa.ai/screenshots/abc123.png",
        "code": null,
        "is_domain_specific": false,
        "screenId": "s_checkout",
        "source": "//*[@id=\"main-cta\"]",
        "sourceKind": "browser"
      },
      {
        "title": "Checkout pay button",
        "url": "src/features/checkout/PayButton.tsx",
        "x_path": "",
        "screenshot": null,
        "code": null,
        "is_domain_specific": false,
        "screenId": "s_checkout",
        "source": "src/features/checkout/PayButton.tsx",
        "sourceKind": "code"
      }
    ],
    "screens": [
      {
        "screenId": "s_checkout",
        "title": "Checkout",
        "url_pattern": "https://app.yourcompany.com/checkout",
        "default_url": "https://app.yourcompany.com/checkout",
        "is_dynamic": false,
        "screenshot": null,
        "component_view_count": 2
      }
    ]
  },
  "_metadata": {
    "lastSyncedAt": "2026-11-09T18:00:00.000Z",
    "source": "infa-cli",
    "boardId": "b_abc12345",
    "stories": { "src/components/Button.stories.tsx": ["mc_abc12345"] }
  }
}
Each view says where it is and which element it is: screenId (the board screen, or null), source (an XPath for a usage found in the browser, a repo-relative file path for one found in code) and sourceKind ("browser", "code" or null). A file written before these fields still works: the panel reads page_id / screen_id as screenId and a component's pages as screens, and takes source from x_path, else from a url that is a file path rather than a page.
infa storybook sync also writes each component's board_url and flows, and each view's is_default, preview_html_url and health (see the types below).
TypeScript Types
The addon includes full TypeScript definitions:
interface ComponentData {
  title: string;
  description: string | null;
  query: string | null;
  external_links: ExternalLink[];
  labels: Label[];
  component_views: ComponentView[];
  // Written by `infa storybook sync`; absent otherwise
  main_component_id?: string;
  screens?: Screen[]; // the board screens its usages sit on
  board_url?: string; // https://infa.ai/b/<board>/components/<mc_id>
  flows?: { id: string; name: string; url: string; reasons?: string[] }[];
}

interface ComponentView {
  title: string;
  url: string;
  x_path: string;
  screenshot: string | null;
  code: string | null;
  is_domain_specific: boolean;
  screenId: string | null; // the board screen the usage is on
  source: string | null; // an XPath (browser) or a repo-relative file path (code)
  sourceKind: "browser" | "code" | null; // read from source: an XPath is "browser"
  id?: string;
  // Written by `infa storybook sync`; absent otherwise
  is_default?: boolean;
  preview_html_url?: string;
  health?: { state: "verified" | "recovered" | "stale" | "broken" | "removed"; checkedAt?: string; reason?: string };
}

interface Screen {
  screenId: string;
  title: string;
  url_pattern: string;
  default_url: string | null;
  is_dynamic: boolean;
  screenshot: string | null;
  component_view_count: number | null;
}

// The file's `_metadata` (not a component)
interface UsageMetadata {
  lastSyncedAt?: string;
  source?: "infa-cli";
  boardId?: string;
  stories?: Record<string, string[]>; // story file (relative to where Storybook runs) → component ids
}

interface Label {
  title: string;
  description: string | null;
  color: string;
}

interface ExternalLink {
  title: string;
  url: string;
}

type UsageDataMap = Record<string, ComponentData>;
See node_modules/storybook-infa-usage/dist/types.d.ts for full definitions.
Getting Infa Main Component IDs
With infa storybook sync you usually need none: a component published with infa publish is linked to its story by the CLI. You need an id only for a component tagged in your product (no file in your repo). Ids look like mc_abc12345 and are in:
- The component's URL on the board (
https://infa.ai/b/<board>/components/mc_abc12345) - Infa API responses
- Browser extension when tagging components
Remember: Once tagged, your component deep links work forever—even if you pause your subscription later. You'll retain access to all the usage data you've already captured.
Custom Data Sources (Advanced)
While this addon is designed for Infa, you can use custom data sources by creating your own integration script. The addon simply reads from src/data/usage-data.json—it doesn't care how the file was generated.
Custom Integration Example
// scripts/custom-integration.js
const fs = require("fs");

async function fetchFromYourAPI() {
  // Your custom logic here
  const response = await fetch("https://your-api.com/components");
  const data = await response.json();

  // Transform to the expected format
  const usageData = {};
  data.forEach((component) => {
    usageData[component.id] = {
      title: component.name,
      description: component.docs,
      query: component.selector,
      external_links: [],
      labels: [],
      component_views: component.instances.map((instance) => ({
        title: instance.name,
        url: instance.url,
        x_path: instance.xpath,
        screenshot: instance.screenshot,
        code: null,
        is_domain_specific: false,
        screenId: instance.screenId ?? null,
        source: instance.xpath, // or a repo-relative file path for a usage found in code
        sourceKind: "browser",
      })),
    };
  });

  fs.writeFileSync(
    "src/data/usage-data.json",
    JSON.stringify(usageData, null, 2),
  );
}

fetchFromYourAPI();
Note: Infa provides the most comprehensive design system usage data, including automated component detection, screenshot generation, and deviation tracking.
Development
Running the Example Storybook
npm install
npm run storybook
Development Mode with Auto-Rebuild
For development with automatic rebuilding when you make changes to the addon:
npm run start
This runs both the addon build in watch mode and Storybook in parallel. Changes to addon source files will automatically rebuild and reload in Storybook.
Building the Addon
npm run build
API Reference
Story Parameters
Add the usage parameter to your story metadata:
interface UsageParameters {
  mcComponentIds?: string[]; // optional when `infa storybook sync` links the story
}
Usage:
parameters: {
  usage: {
    mcComponentIds: ["mc_id1", "mc_id2"];
  }
}
Troubleshooting
Panel shows "No Usage Data"
- Run
npx infa storybook syncand read what it prints: each story with the components it found. A story it lists with none has no component on the board yet — publish one withnpx infa publish <Component.tsx>, or name it inmcComponentIds - Restart Storybook after syncing
- Run Storybook from the folder you ran the sync in: stories are matched by their path relative to it
- Confirm
src/data/usage-data.jsonexists and contains your component IDs (or set the addon'sdataFileoption)
Component shows "Unknown Component"
- The component ID exists in story parameters but not in
usage-data.json - Check that the ID format is correct (e.g.,
mc_abc12345) - Run
npx infa storybook syncto update the data file; it names every id it could not read and why - Check you are signed in as someone who can read that board (
npx infa auth status)
Data not updating
- Restart or rebuild Storybook after updating
usage-data.json: the addon reads it when Storybook starts - Clear your browser cache if old data persists
- Check the browser console for any errors
- Verify the data file is being bundled correctly (check Network tab)
infa storybook sync says "Not authenticated" or "No board configured"
- Run
npx infa auth, thennpx infa board, in your project's root. - In CI, set
INFA_ACCESS_TOKENandINFA_BOARD_ID.
infa-usage-fetch fails with "Invalid API key or API key not found"
Infa received a key it does not recognise:
- Copy the token with its copy button on infa.ai/profile?tab=integrations; the visible
abcd****is a masked preview, not the key. - The key goes in the
x-api-keyheader (infa-usage-fetchdoes this for you), notAuthorization: Bearer. - No spaces or line breaks around it.
infa-usage-fetchtrims them; your own code should too. - A deleted token stops working at once; generate a new one.
infa-usage-fetch says some components were "Not returned"
The token reads components on boards its own account owns. Check the mc_… id and that the token was made by the board's owner — or switch to npx infa storybook sync, which reads as you and covers team boards.
Empty Component Views
- Verify components have been tagged in Infa
- Check that you're using the correct main component IDs
- Ensure the component has been detected in at least one product page
- Try re-syncing data in your Infa dashboard
Resources
- Infa External API
- Get Your Infa API Key (Profile → Integrations → Personal Access Tokens)
- Storybook Documentation
Contributing
Contributions are welcome! Please feel free to submit a Pull Request.
License
MIT
- infa_ai
